

One visual noun
A face, object, place, or result—not six competing signals.
GPT Image 2 currently leads the live text-to-image ranking and is the strongest evidence-based starting point for YouTube thumbnail concepts. Still test the top three at 16:9: a general image winner is not automatically best at faces, text-safe composition, or click-through rate.
Updated October 4, 2026 · 9,564 displayed-model comparisons · No paid placement
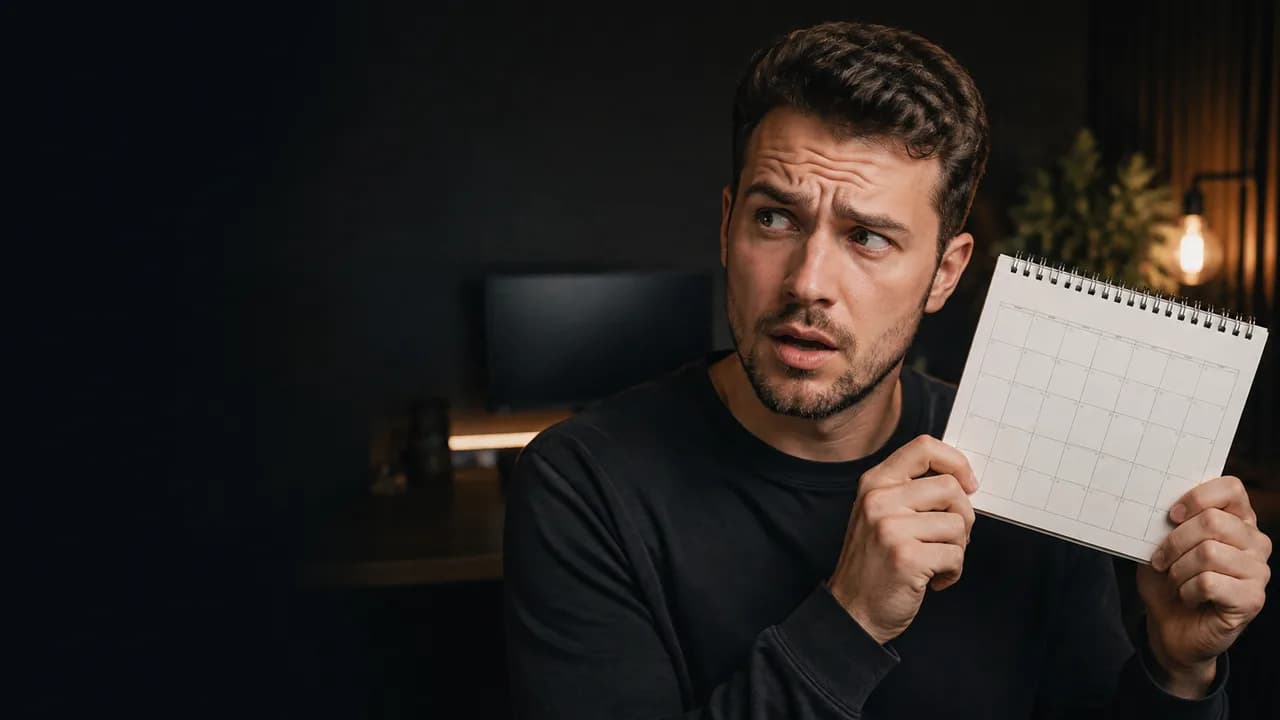
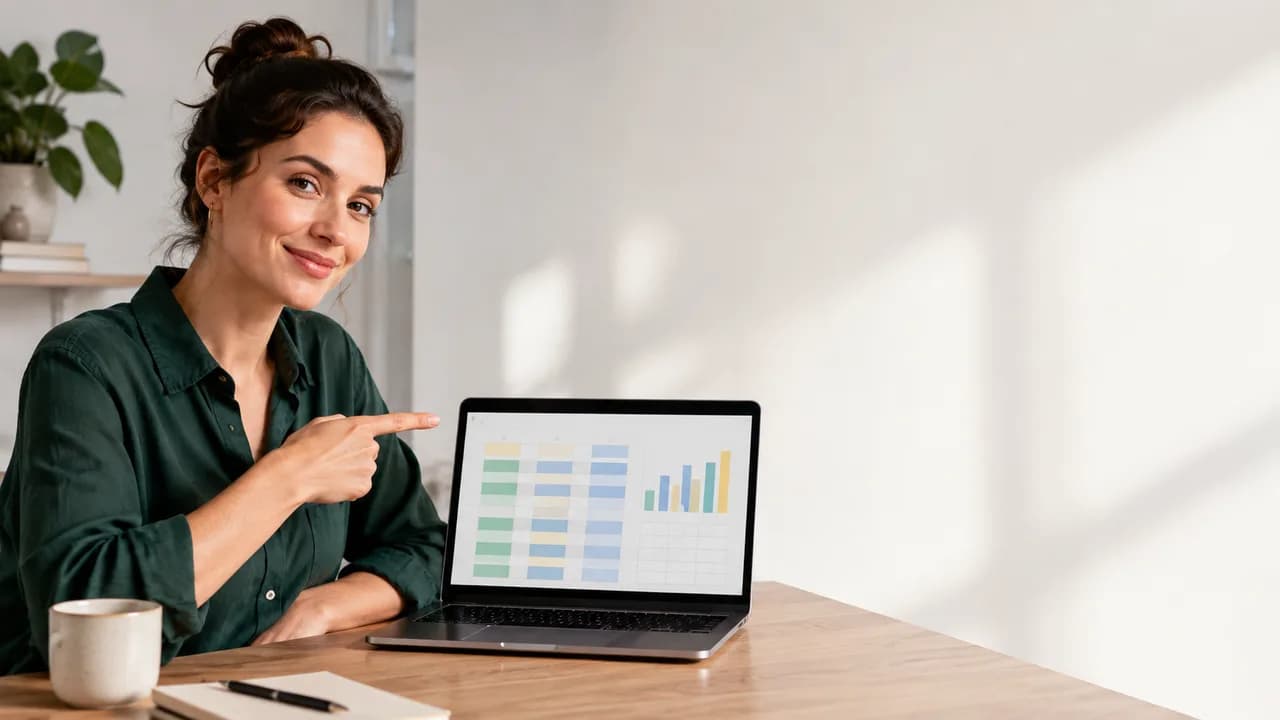
1
focal idea
3–5
overlay words
10%
size check
 Reviewed by Jonathan Chavez · 9,564 blind comparisons across the displayed image modelsSources & review
Review boundary
Ranking methodology reviewed internally; thumbnail concepts have not been validated against channel analytics or reviewed by YouTube.
Scope and disclosure
The ranking measures general text-to-image preference, not YouTube click-through rate. Original concepts on this page illustrate evaluation criteria and are not arena results. LLM Stats accepts no payment for ranking position. Read the methodology or report a correction.
Ranked by conservative TrueSkill from blind image comparisons. A model needs both wins and sufficient evidence to rise; model names are hidden during voting.

openai
Arena score
506
Comparisons
115
Price signal
$0.05/image
Arena score
362
Comparisons
24
Price signal
$0.04/image

microsoft
Arena score
257
Comparisons
97
Price signal
$0.05/image
openai
Arena score
251
Comparisons
4,697
Price signal
$0.05/image

Arena score
154
Comparisons
358
Price signal
$0.02/image
sourceful
Arena score
150
Comparisons
103
Price signal
$0.15/image

black-forest-labs
Arena score
72
Comparisons
1,259
Price signal
$0.02/image
Arena score
66
Comparisons
2,911
Price signal
$0.04/image
These are original editorial examples generated for this guide. The background contains no baked-in copy; headlines are HTML overlays so the typography stays sharp, accessible, and easy to change.
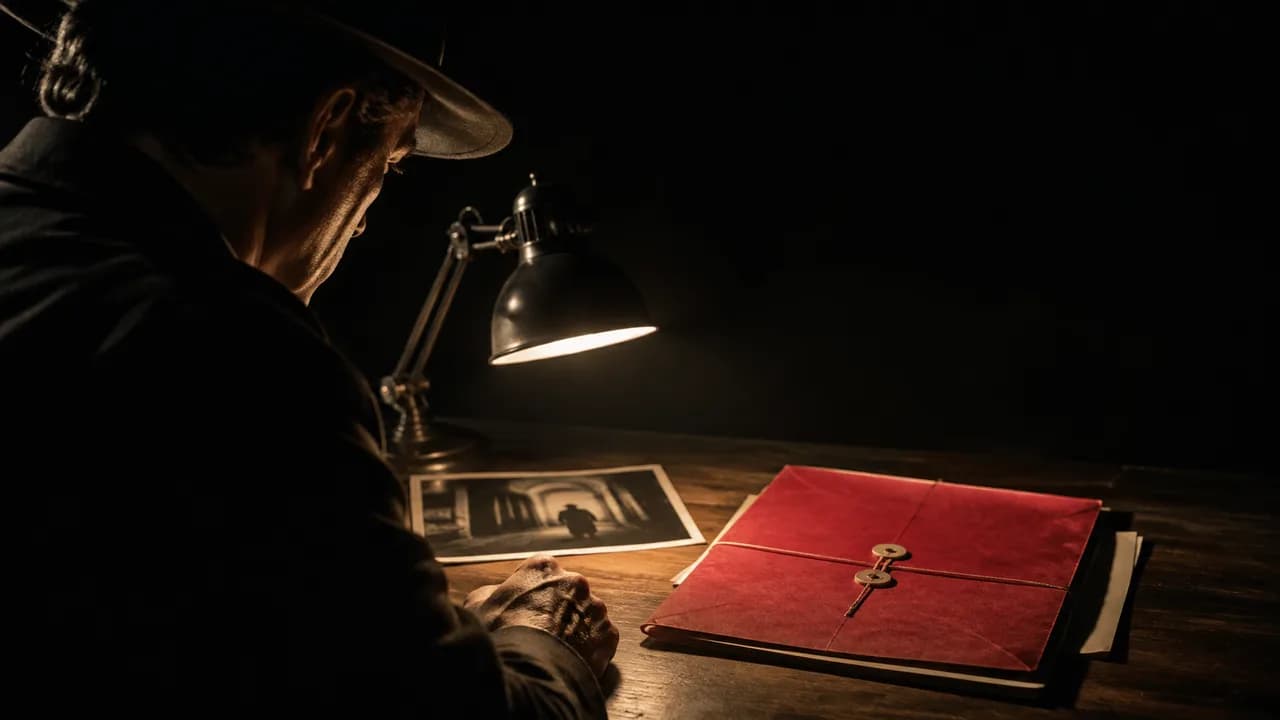
More detail rarely means more clarity. At feed size, viewers should recognize the subject, feel the tension, and understand what kind of payoff the video offers.
A face, object, place, or result—not six competing signals.
Light, color, scale, and empty space should isolate the subject.
The image adds information instead of repeating the video title.
Curiosity comes from a real gap the video will close.
Give every finalist the same brief and request four genuinely different compositions. Add typography outside the image model, then inspect at 10% size before any audience test.
Can a viewer predict the video’s payoff in one glance?
Is there one unmistakable focal point at phone size?
Does the subject stay clear against the background?
Is there clean space for three to five large words?
Does the image represent content the video actually delivers?
Can the workflow produce meaningfully different concepts, not recolors?
CTR must be interpreted with impressions, traffic source, audience, title, topic, publication timing, and watch behavior. Do not declare a model winner from one thumbnail on one video.