
Nemotron 3.5 Lightning: NVIDIA's Fast 30B-A3B Agent Execution Model
Nemotron 3.5 Lightning is NVIDIA's open 30B MoE (~3B active) for agent execution layers—tool calls, validation, and subagent work—under OpenMDW-1.1 with NeMo Switchyard routing.
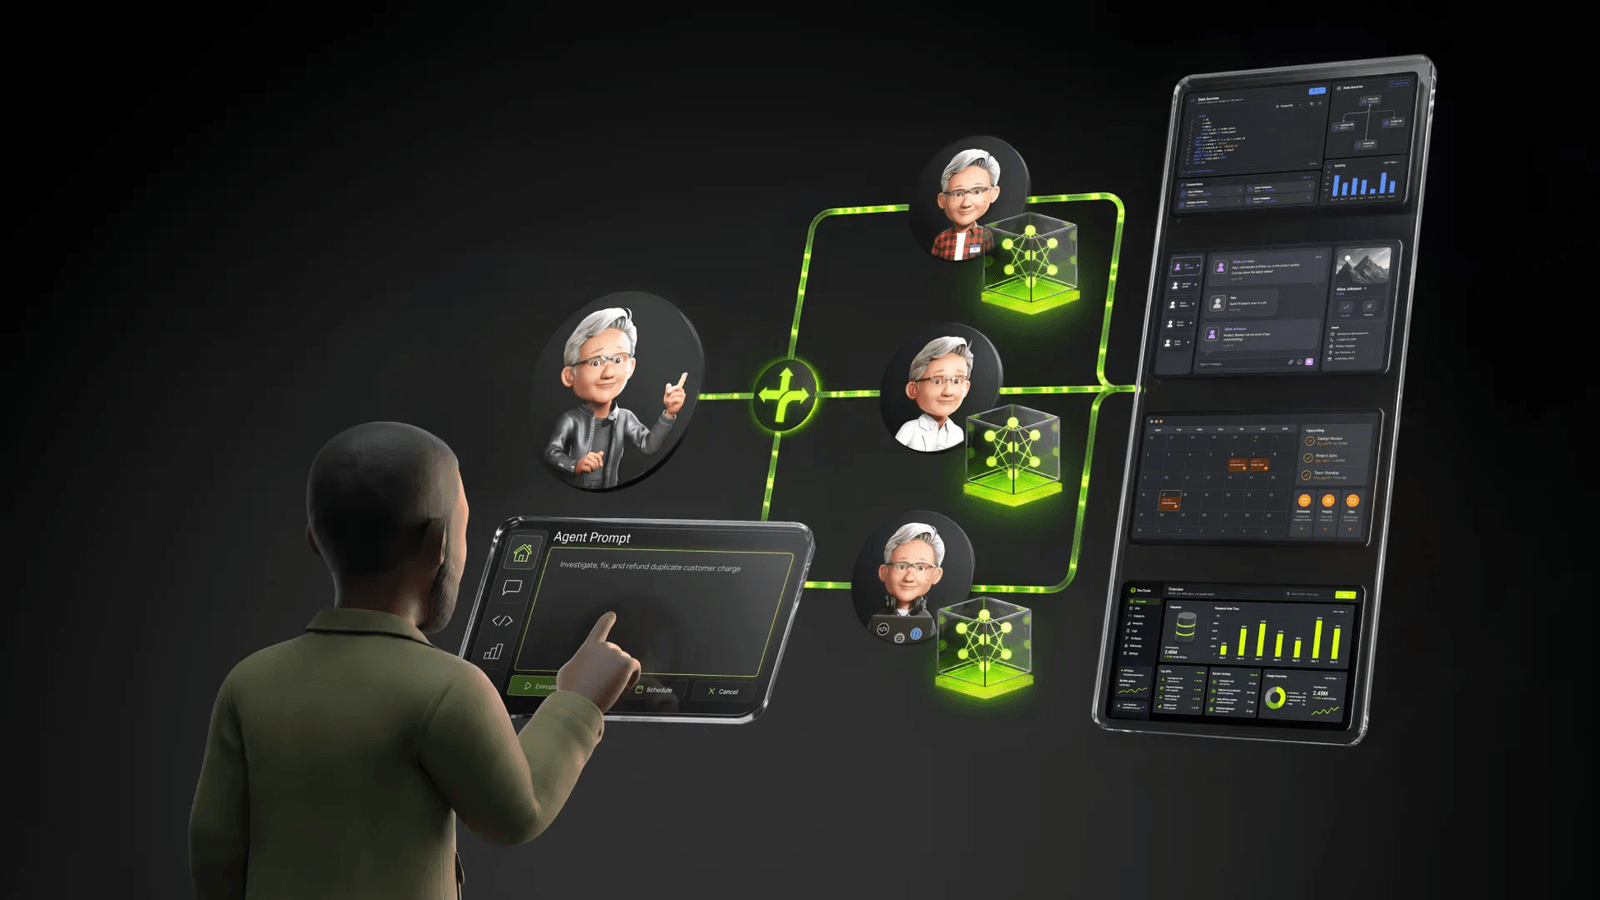
Long-running agents burn most tokens on high-volume, low-glamour steps. Using a frontier reasoner for every git status and tool parse is how bills and latency explode. Lightning is NVIDIA's open answer to that layer.
At a Glance
- Release date: August 11, 2026
- Catalog / HF ids:
nemotron-3.5-lightning-30b-a3b; Hugging Facenvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16and-NVFP4 - Organization: NVIDIA
- Architecture: Hybrid MoE (Mamba-2 + MoE + Attention); 30B total / ~3B active
- Context: Up to 1M tokens (HF notes ~256K practical on a single H100)
- Modalities: Text in / text out
- License: OpenMDW-1.1 (weights, data, recipes; permissive commercial use per NVIDIA)
- Checkpoints: BF16 (customize) + NVFP4 (deploy)
- Speculative decoding: MTP baked in; ships with DSpark and DFlash draft helpers
- Hosting: build.nvidia.com, OpenRouter, and multiple inference providers
- API list price: Open weights; hosted $/token varies by provider (TBD in catalog)
What's Actually New
1. Execution-layer MoE, not a mini-frontier
Distilled from Nemotron 3 Ultra; harness-oriented training. Ultra/Super plan; Lightning runs the loop.
2. NeMo Switchyard companion story
Router so frontier takes hard plans and Lightning takes high-volume execution.
3. Open drop day-of
HF/ModelScope weights + data + recipes under OpenMDW-1.1. Local: DGX Spark, RTX 5090, Jetson; LM Studio, llama.cpp, Ollama, Unsloth, vLLM, SGLang, TRT-LLM.
Benchmarks (label carefully)
| Signal | Number | Caveat |
|---|---|---|
| Output speed vs similar size | Up to 4x | NVIDIA self-reported |
| PinchBench | 86%; ~30% faster than Qwen3.6 35B at similar accuracy | NVIDIA self-reported |
| Terminal-Bench 2.1 | ~24.6 (press) | Weak as primary agent; use as executor |
| LLM Stats verified | Pending |
Pricing & Availability
Open weights. Hosted TBD by provider. Docs: https://developer.nvidia.com/blog/nvidia-nemotron-3-5-lightning-delivers-fast-accurate-specialized-task-execution-for-long-running-agents/
When to Use It
Good: subagents / high-volume tool loops / local fine-tunes. Not: primary coding agent needing top Terminal-Bench. Practical question: do you need Ultra-class reasoning, or another fast correct tool call?
Outlook
Productizes "small model does the chores." Compare cost/latency per accepted tool step vs Qwen3.6-class MoEs and gpt-oss-120b, not vs Opus planners.
Sources: NVIDIA developer blog; HF BF16 card; SGLang Day-0.
Questions
Frequently Asked Questions
August 11, 2026.
- It is a hybrid MoE with about 30B total and ~3B active parameters (
nemotron-3.5-lightning-30b-a3b). - OpenMDW-1.1 for weights, data, and recipes (permissive commercial use per NVIDIA).
- Up to 1M tokens; Hugging Face notes about 256K practical on a single H100.
A routing companion so frontier models take hard plans and Lightning handles high-volume execution.
Continue Reading